Can your agent find the bugs maintainers fix? In PROBE, coding agents are tasked to audit a whole repository for bugs. We compare their findings against 2,457 bugs that maintainers fixed over the following 18 months.
2,457 reference bugs across 20 repositories. Models use PROBE audit harness.
PROBE model results. Use the column buttons to sort. All percentages are relative to the maintainer-fixed reference set.
#
01
DeepSeek V4.1 Flashhigh
10.5 percent
15.2 percent
8.1 percent
5,019
$73
F1
10.5%
Recall
15.2%
Precision
8.1%
Findings
5,019
Cost
$73
Reasoning
high
02
GPT-5.6 Solhigh
10.2 percent
20.8 percent
6.7 percent
8,285
$1,185
F1
10.2%
Recall
20.8%
Precision
6.7%
Findings
8,285
Cost
$1,185
Reasoning
high
03
GPT-5.6 Lunaxhigh
10.1 percent
17.3 percent
7.1 percent
6,636
$131
F1
10.1%
Recall
17.3%
Precision
7.1%
Findings
6,636
Cost
$131
Reasoning
xhigh
04
GLM 5.3 Flashhigh
9.7 percent
15.8 percent
7.0 percent
6,029
$120
F1
9.7%
Recall
15.8%
Precision
7.0%
Findings
6,029
Cost
$120
Reasoning
high
05
GPT-5.6 Solmedium
9.6 percent
16.9 percent
6.7 percent
6,675
$678
F1
9.6%
Recall
16.9%
Precision
6.7%
Findings
6,675
Cost
$678
Reasoning
medium
06
GPT-5.6 Lunahigh
9.0 percent
13.0 percent
6.9 percent
5,017
$55
F1
9.0%
Recall
13.0%
Precision
6.9%
Findings
5,017
Cost
$55
Reasoning
high
07
GPT-5.6 Sollow
9.0 percent
11.4 percent
7.5 percent
3,903
$276
F1
9.0%
Recall
11.4%
Precision
7.5%
Findings
3,903
Cost
$276
Reasoning
low
08
GPT-5.4medium
8.5 percent
11.0 percent
6.9 percent
4,204
$655
F1
8.5%
Recall
11.0%
Precision
6.9%
Findings
4,204
Cost
$655
Reasoning
medium
09
GPT-5.6 Terramedium
8.3 percent
9.1 percent
7.6 percent
3,093
$224
F1
8.3%
Recall
9.1%
Precision
7.6%
Findings
3,093
Cost
$224
Reasoning
medium
10
Gemini 3.5 Flashmedium
7.8 percent
9.8 percent
6.4 percent
3,867
$493
F1
7.8%
Recall
9.8%
Precision
6.4%
Findings
3,867
Cost
$493
Reasoning
medium
11
Muse Spark 1.3*high
7.4 percent
15.9 percent
4.8 percent
8,372
$164
F1
7.4%
Recall
15.9%
Precision
4.8%
Findings
8,372
Cost
$164
Reasoning
high
12
GPT-5.6 Luna*medium
7.3 percent
7.6 percent
7.0 percent
2,774
$15
F1
7.3%
Recall
7.6%
Precision
7.0%
Findings
2,774
Cost
$15
Reasoning
medium
13
Claude Sonnet 5medium
6.7 percent
7.9 percent
5.8 percent
3,472
$421
F1
6.7%
Recall
7.9%
Precision
5.8%
Findings
3,472
Cost
$421
Reasoning
medium
14
GPT-5.6 Lunalow
5.8 percent
5.3 percent
6.5 percent
2,027
$8
F1
5.8%
Recall
5.3%
Precision
6.5%
Findings
2,027
Cost
$8
Reasoning
low
Tap a row for detailed scores.
F1 score
Harmonic mean of recall and precision. Higher is better.
Recall
Share of reference bugs recovered by the agent. Higher is better.
Precision
Share of agent findings matching the reference set. Unmatched findings may still be valid.
Findings
Total bug findings reported by the agent across the benchmark, including reports that do not match the reference set.
Cost
API cost in US dollars for one full benchmark run.
GPT-5.6 Luna (medium) and Muse Spark results are means over 10 and 5 runs, respectively. Other configurations use one run. Different reasoning efforts are listed separately.
THE BENCHMARK
What is PROBE?
We use the bugs maintainers actually fixed to evaluate what an agent could have found months earlier.
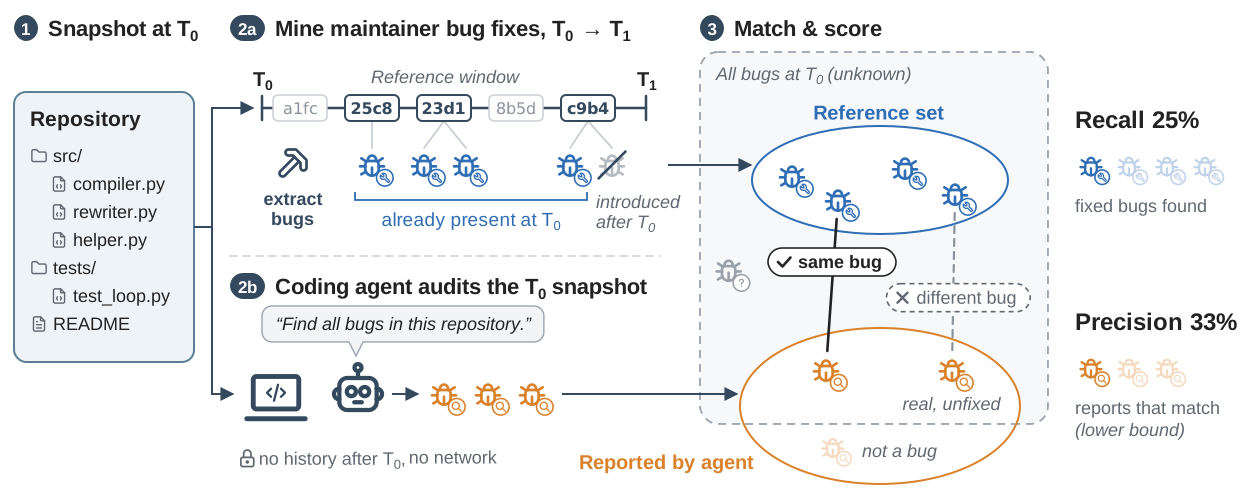
Overview of PROBE. We snapshot a repository at T₀. In parallel, we mine maintainer fixes during the reference window T₀ → T₁ and ask a coding agent to audit the original snapshot. Only fixed bugs already present at T₀ enter the reference set. We then match agent reports against that set to compute recall and precision.
↳
An open world needs a partial reference. A bug absent from the reference set is not necessarily a false positive. Maintainers may not have fixed it yet. We independently assess validity to make that distinction.
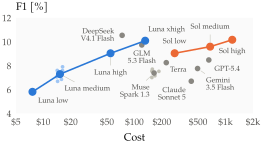
F1 scores against the maintainer-fixed reference set versus API cost. Luna (blue) and Sol (orange) are connected across reasoning efforts; faint markers show reruns.
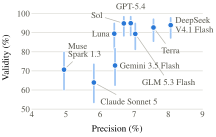
Panel-assessed bug validity versus precision against the reference set, with 95% confidence intervals. For every evaluated model, the panel confirms over 60% of assessed findings as real bugs, excluding inconclusive cases.
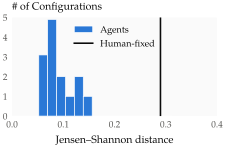
Jensen–Shannon distance of each agent configuration’s bug-type distribution to other runs, compared with the human-fixed reference set. Agents are more similar to one another than to maintainer fixes.
Proactive bug discovery is an important software-engineering problem, yet the ability of coding agents to find the bugs that human maintainers would repair across an entire repository remains understudied. PROBE measures this capability using 2,457 bugs fixed over 18 months across 20 diverse repositories.
Agents find many valid bugs, but their findings follow a different distribution from maintainer fixes. The benchmark makes this gap measurable and provides a reference for improving repository-wide bug discovery.
The PROBE benchmark dataset will be available on Hugging Face.
Dataset forthcoming
Citing PROBE
If you use PROBE in your research, please cite this work.
BIBTEX
@misc{paina2026probe,
  title  = {PROBE: Frontier Coding Agents Find Different Bugs Than Maintainers Fix},
  author = {Marco Paina and Mark Müller and Niels Mündler-Sasahara and Martin Vechev},
  year   = {2026},
  url    = {https://probebench.com}
}
 PROBE